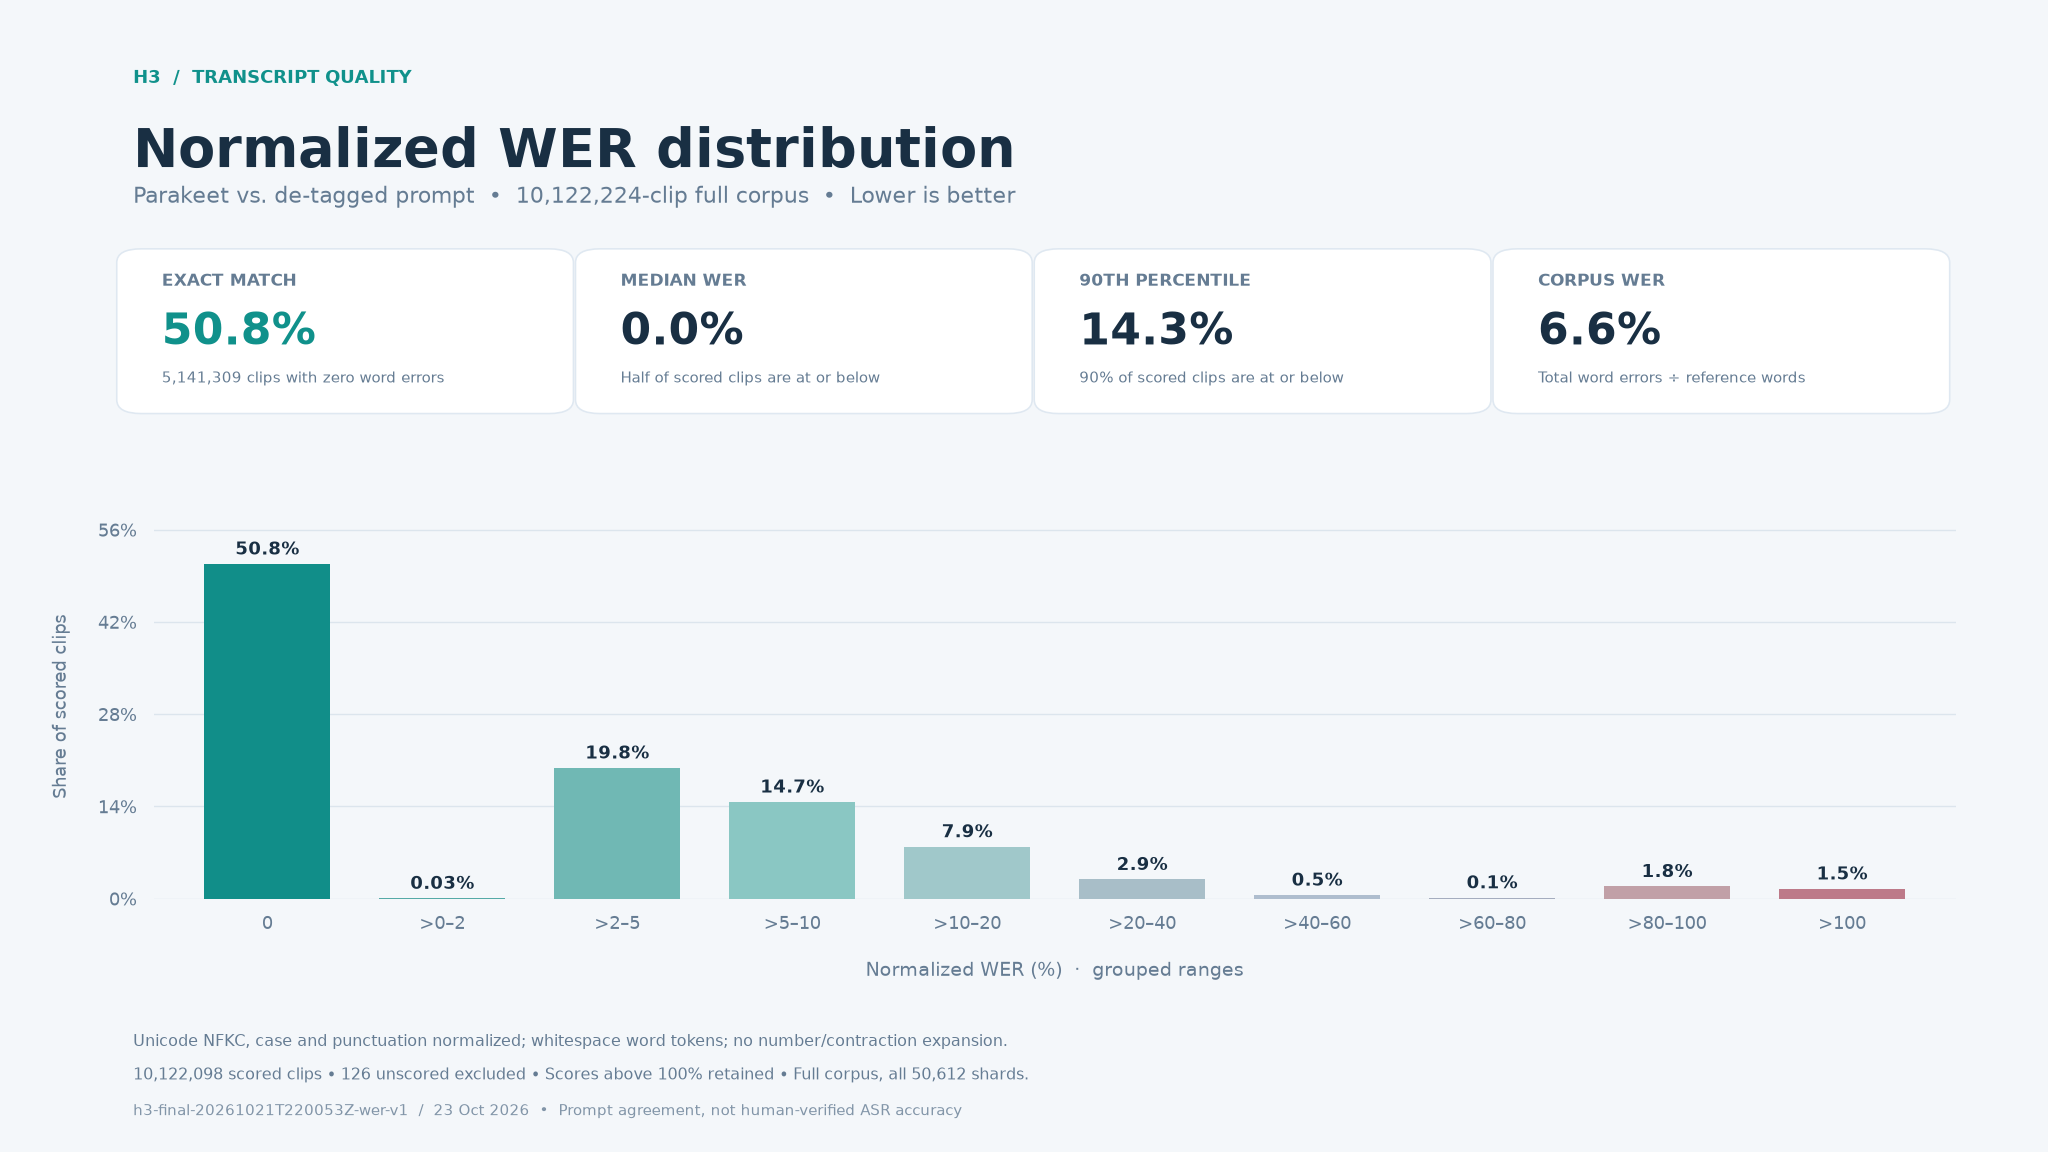
Compare the Parakeet transcript with the de-tagged generation prompt. These metrics cover the full backfill, separately from the 2,000-query embedding diagnostic.
6.61%Total normalized word errors ÷ reference words.
50.8%5,141,309 clips have zero normalized word errors.
14.3%90% of scored clips are at or below this value.
A complete-corpus distribution, not a small sample. Scores above 100% are retained. Download figure PDF ↗
Two averages, two questions
6.61% corpus WER. 13.95% mean clip WER.
The corpus metric sums word errors and reference lengths, so longer word sequences carry more weight. The clip mean gives each defined clip rate equal weight. These are different summaries of the same measured results.
Raw corpus WER is 30.37%; normalized character error rate is 3.33%. Case and punctuation account for a substantial part of the raw word mismatch.
Interpretation
Prompt agreement, not a human label.
The reference is the intended generation script. Unicode NFKC, case, punctuation and whitespace are normalized. Numbers are not expanded, contractions are not rewritten, and accents are retained.
WER uses whitespace tokens. It is not linguistic word segmentation for languages such as Japanese or Chinese; normalized CER helps interpret those clips. Empty denominators produce null rates, not fabricated zeros.